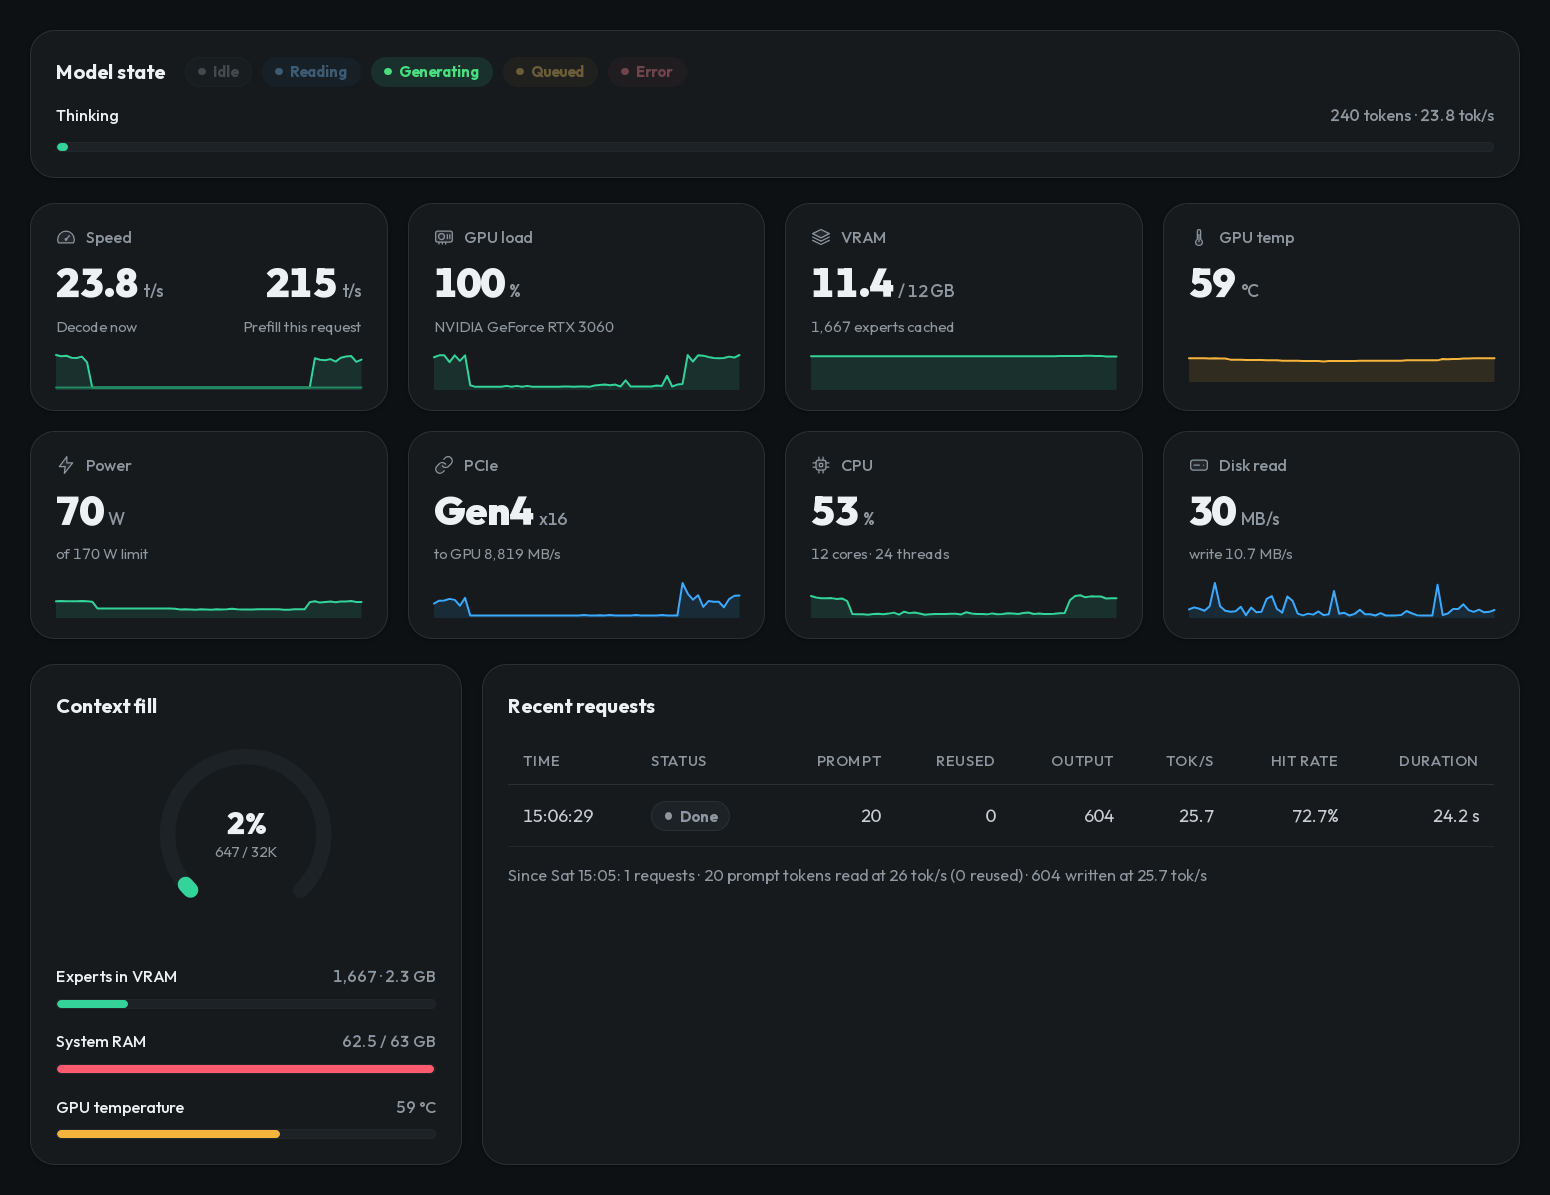
If you want to experiment with LLMs, you typically have a choice of sending your requests to someone else’s computer or fielding a very large GPU and CPU setup to …. A recent crop of projects aims to bring bigger models to much more modest hardware. One example is Strata, a project from [Niko1221], which lets you run a 125-billion-parameter LLM on hardware you might already have for gaming.
It won’t run on your old Pentium laptop, but it doesn’t require a supercomputer-like farm of graphics cards, either. Strata can use several Qwen3.8 model variants, including different quantizations of the original model as well as coding and other specialized versions. Qwen3.8-Flash-Next is a mixture-of-experts model containing 24,576 small experts, of which only ten are needed for each token.
The clever part is that Strata effectively treats VRAM as a cache for the much larger model. Frequently used experts stay on the GPU, while the complete collection normally remains in system RAM.
Discover more from ChuckysCarnage
Subscribe to get the latest posts sent to your email.

